/01
Private AI
Owning the model you use: offline, on your hardware, on your terms.
/02
AI for upskilling
Using AI to get better at real things: languages, training, the conversation that matters.
/03
On-device future
Small models, phone chips, and the measurements most benchmarks skip.
Nov 5, 2026
A practice rep only counts if you had to produce the sentence
Recognition is cheap to grade and feels like progress. Here is how to set up practice that makes you produce language, and how to tell when a rep didn't count.
Read on Substack ↗
Nov 3, 2026
If your eval has never failed, it isn't measuring anything
How to test an LLM eval before you trust it: one input that must score badly, one that must score well, and the gap between them.
Read on Substack ↗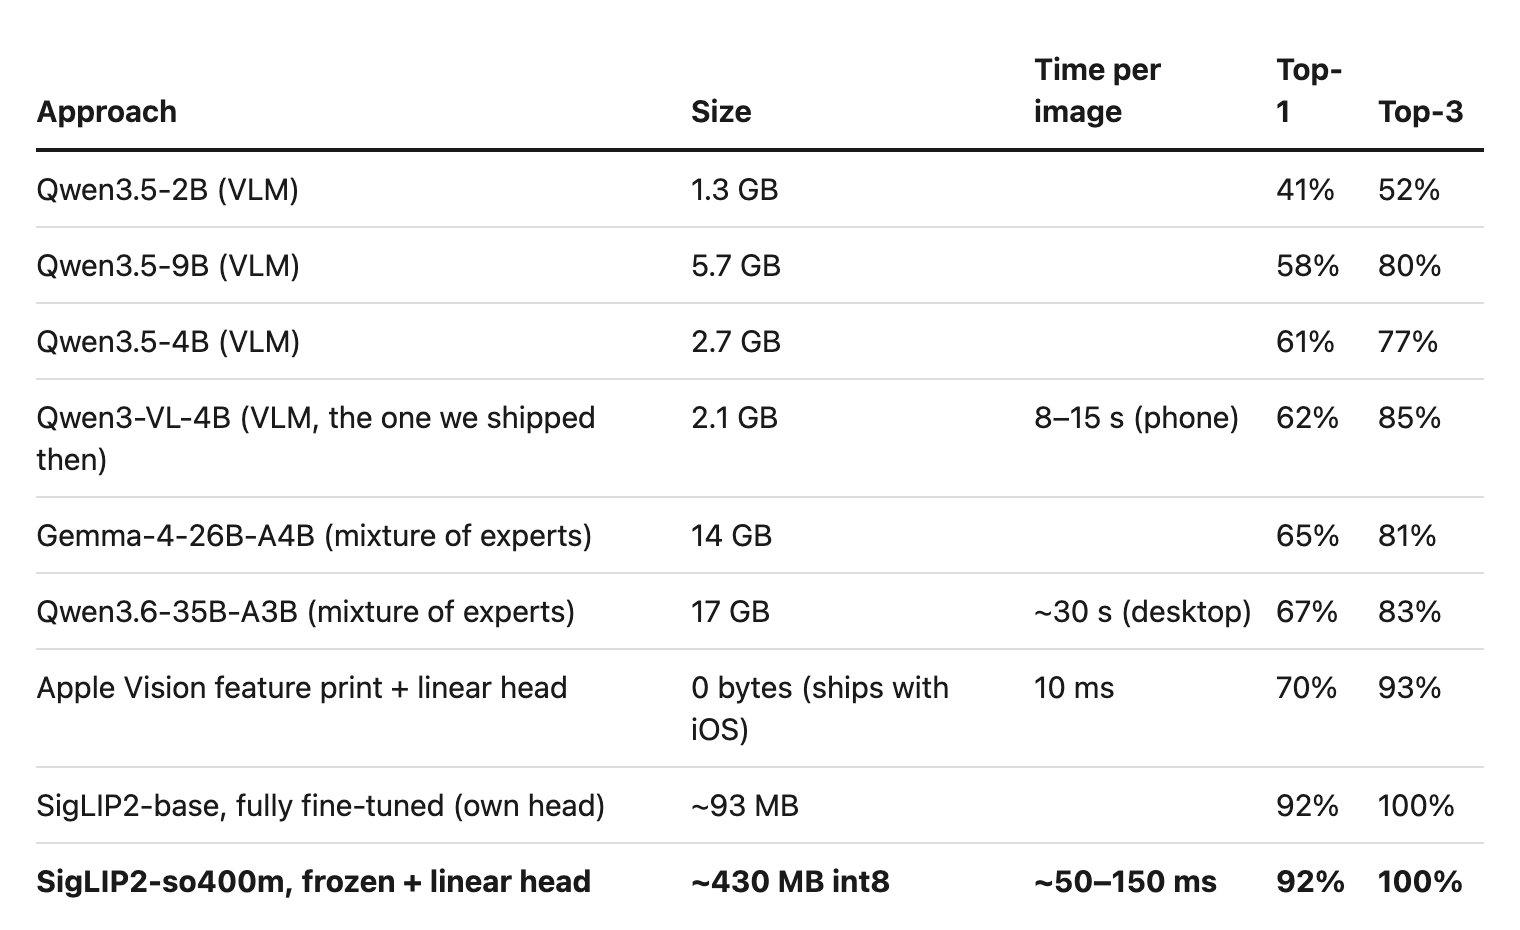
Oct 20, 2026
Nine ways to lose to a linear classifier
We spent five weeks trying to beat a frozen encoder with a VLM. Here is how each attempt lost, and what to do instead.
Read on Substack ↗
Oct 15, 2026
Let an AI choose your exercises, never your numbers
An AI workout plan is good at picking movements and bad at sets, weights and schedules. Here is how a beginner can split the job.
Read on Substack ↗
Oct 13, 2026
A small model follows the list you show it, not the rules you write
If your local LLM ignores instructions, a sterner prompt and a bigger model won't fix it. Change what the model sees.
Read on Substack ↗